The Most Seasoned Partner for the AI Era, AIMTOG


OPERATION
AI DATA CENTER · 03
From a single server to a GPU cluster,
we've run it all without interruption
Operations capability is proven not by claims, but by scale. From x86 servers and storage to the latest GPU clusters, AIMTOG has taken responsibility for the entire process of bringing deployed infrastructure online and maintaining it.
-
200,000+
Cumulative x86 · Storage · GPU deployed
-
2,000+
GPUs under cumulative management
-
99.9%
SLA compliance rate
-
On-site
Dedicated engineers stationed at customer IDCs
Operation Scope
We take responsibility for everything from infrastructure build to maintenance
From server and storage deployment to GPU cluster builds — and the maintenance that keeps all of it running — AIMTOG operates the full infrastructure lifecycle as a single, unified system.
-
01
Compute infrastructure
x86 servers · GPU servers
From general-purpose x86 servers to high-performance GPU servers, we supply and install compute resources matched to the workload. This is a domain we've worked in for over 20 years, across a cumulative 200,000+ systems.
-
02
Storage & data
All-Flash · HCI
We build the storage layer that feeds data to compute. All-Flash high-performance storage and HCI integrated infrastructure support large-scale data pipelines.
-
03
Maintenance & operations
dedicated on-site · paid maintenance
It doesn't end at deployment. Through dedicated maintenance contracts and on-site operations, we continuously ensure stable operation from servers to GPU clusters.
Nationwide Technical Support
Technical support hubs that reach anywhere in the country
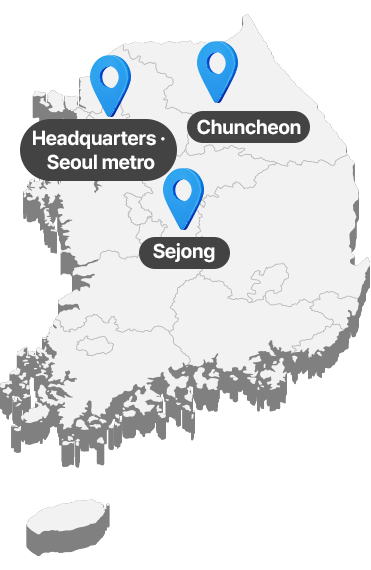
Incidents don't pick a location. AIMTOG operates three domestic technical support hubs, centered on the Seoul metropolitan area, with a rapid on-site response system built for data centers nationwide.
-
SUPPORT HUBS
- Headquarters · Seoul metro hub
- The center of the technical support organization. It oversees all hubs and directs emergency response.
- Chuncheon hub
- On-site support for high-density GPU clusters, including NAVER's Chuncheon IDC.
- Sejong hub
- On-site response for central-region data centers, including NAVER's Sejong IDC.
Build & Stabilize
Cases we built and stabilized ourselves
This isn't simple delivery — we've carried out the build and stabilization directly. We've accumulated experience designing and building clusters of varying scale and workload, validating performance, and handing them over in a stable running state.
-
NAVER HyperCLOVA X
Ultra-large LLM infrastructure
InfiniBandUltra-large LLM infrastructure build, standardization, and stabilization support
-
Kakao Brain
AI research cluster
InfiniBandCore infrastructure build; NVLink–IB topology integration and optimization
-
Coupang AI
Commerce AI infrastructure
RoCE400GbE RoCE v2/RDMA tuning; GDS-integrated data-transfer optimization
-
Kim & Chang
LLM · RAG · AI development
GDS · RoCELLM, RAG, and AI development infrastructure build; software-stack optimization
-
NC AI
Game AI platform
InfiniBandNative build of a high-performance cluster based on NDR InfiniBand
How We Operate
What we do
Operations isn't about responding when an incident occurs — it's about keeping incidents from occurring. Proactive management and precise diagnostics are the core of on-site operations.
-
Proactive operational stabilization
- Dedicated maintenance framework in operation, with proactive incident response
- Escalated support through manufacturer technical hotlines
- Standardized management of optimal server, GPU driver, and firmware versions
- Operational stabilization through deep-dive incident analysis
-
Performance validation and diagnostics
- Communication-performance validation based on NCCL
- GPU stress testing and system load validation
- Continuous system diagnostics using DCGM
- Interconnect bandwidth and latency validation
We'll review how to stabilize your running GPU environment — together with you.
